
Immediate symptom set
Short delivery lead times stretching into late shipments, inaccurate on-hand counts, and rising labor costs together point to systemic faults in the distribution layer. Practical fixes begin with targeted observation of throughput, SKU accuracy, and retrieval latency — often addressed through FMCG warehouse automation retrofits rather than wholesale process redesigns. The 2020 COVID-19 disruptions exposed how fragile regional networks can be; logistics hubs such as Rotterdam and Singapore showed that a single choke point can cascade across retail shelves and promotions.
Root-cause operational teardown
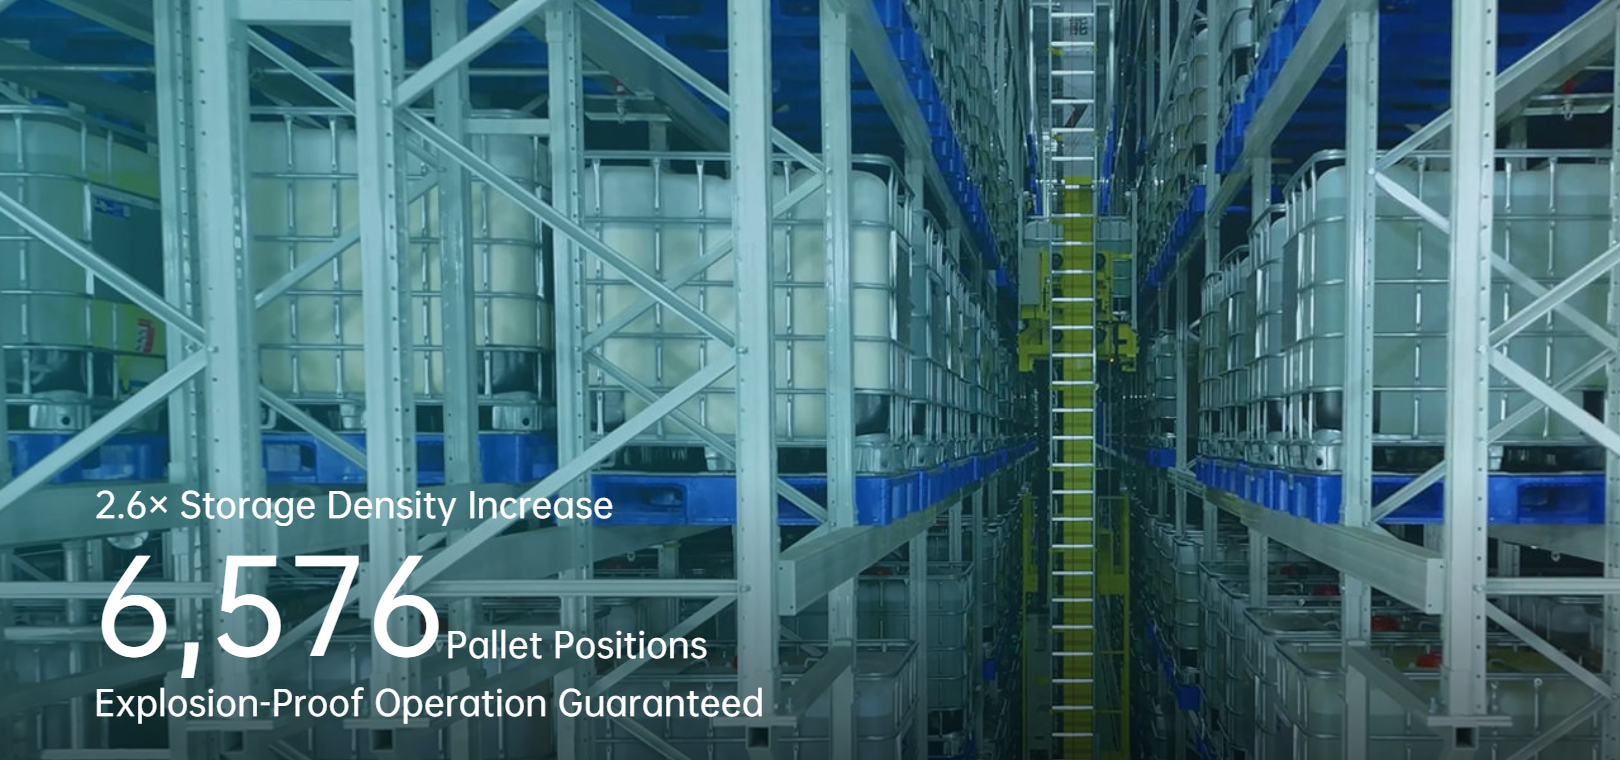
Breakdowns usually fall into three technical buckets: poor inventory visibility, constrained picking capacity, and brittle scheduling. A teardown inspects WMS transaction logs, pick-and-pack cycle times, and replenishment lead-time variance. Include the production teardown data model and embed {main_keyword} and {variation_keyword} within task-level audit trails to keep analysis reproducible. Use short test runs: simulate demand spikes, measure conveyor throughput, and sample SKU mispicks to quantify error rates. The measurable output drives whether to tune software parameters or to invest in hardware like AS/RS modules.
Targeted corrective actions
Apply corrective actions in order of technical return on investment. First, stabilize inventory counts with barcode reconciliation and tighter cycle-count windows; that reduces false stockouts. Second, re-balance pick zones and implement discrete batch picking for high-velocity SKUs to cut travel time. Third, introduce lightweight automation — conveyors, sorters, or pick-to-light — where manual throughput exceeds sustainable labor hours. For long-term resilience, pair these with updated slotting logic and a WMS configuration that supports dynamic replenishment for fast-moving items. Where appropriate, test solutions in a pilot cell within existing fmcg warehousing footprints to observe real-world effects before roll-out.
Common mistakes and avoidance
Teams often overbuild: complex robotics for marginal gains, or they under-invest in integration testing — both waste capital. Another recurring error is ignoring day-to-day exceptions; automation without exception-handling rules increases downtime. — Document exception flows, then automate the high-frequency cases first. Finally, don’t let vendor demos drive decision criteria; require measurable KPIs during a timed pilot and insist on data exports in readable formats for post-test analysis.
Three golden rules for selection and measurement
1) Cycle-time delta per SKU: measure baseline pick-to-ship time and demand a minimum 20% delta from any proposed change. This ties improvements to throughput, not vendor claims.
2) Inventory accuracy across control zones: track count variance by zone; solutions must reduce zone variance below a predefined tolerance within 60 days.
3) Mean time to recover (MTTR) for exceptions: record the time from a failed pick or system fault to full operational state; aim to halve MTTR after process and tool changes.
Apply these rules in trials and weigh cost against sustained operational gain — not theoretical peak performance. The practical endpoint is repeatable week-over-week improvement in order fulfilment and reduced labor spikes, which is where BlueSword delivers measured benefit through tailored retrofit programs and integration expertise. I stand by solutions that prove their gains on the floor, not on slides. Built for supply teams.